The model is not the whole decision
Most AI procurement discussions still begin with the same shortlist. Which model is best? Which one is fastest? Which is cheaper? Which appears most capable on a benchmark? These are legitimate questions. They are not sufficient questions.
An AI model is not a self-contained operating environment. It is reached through an interface or platform; it is run on somebody’s infrastructure; it is connected to data under particular terms; and it is paid for, metered and governed through commercial arrangements that can change. The same model can look radically different depending on which of those surrounding conditions apply.
That is why the idea of “vendor independence” can become misleading so quickly. A business can use open weights while depending entirely on a hosted service. It can self-host a model while depending on a cloud provider’s capacity, region and pricing. It can retain a local copy while being unable to reproduce the data pipeline, safety tooling, technical skills or evidence required to operate it responsibly.
Open may be an important property. It is not the whole architecture.
Six layers of independence
The useful question is not whether a model is open or closed. It is whether the organisation understands the six dependency layers that determine how independently it can actually operate.
None of these questions is technical decoration. Each one reaches into how a business operates when the conditions change.
Model — What licence, version, capability and support assumptions are we making?
Distribution — Who makes the model, datasets, tools or ecosystem available to us?
Infrastructure — Who supplies the compute, capacity, location, reliability and continuity?
Data — Who can process, retain, inspect or learn from the material that moves through the system?
Commercial control — Who sets the price, meters use, audits activity or changes the contractual terms?
Exit — What can we move, how quickly, with what evidence, at what cost and under whose decision?
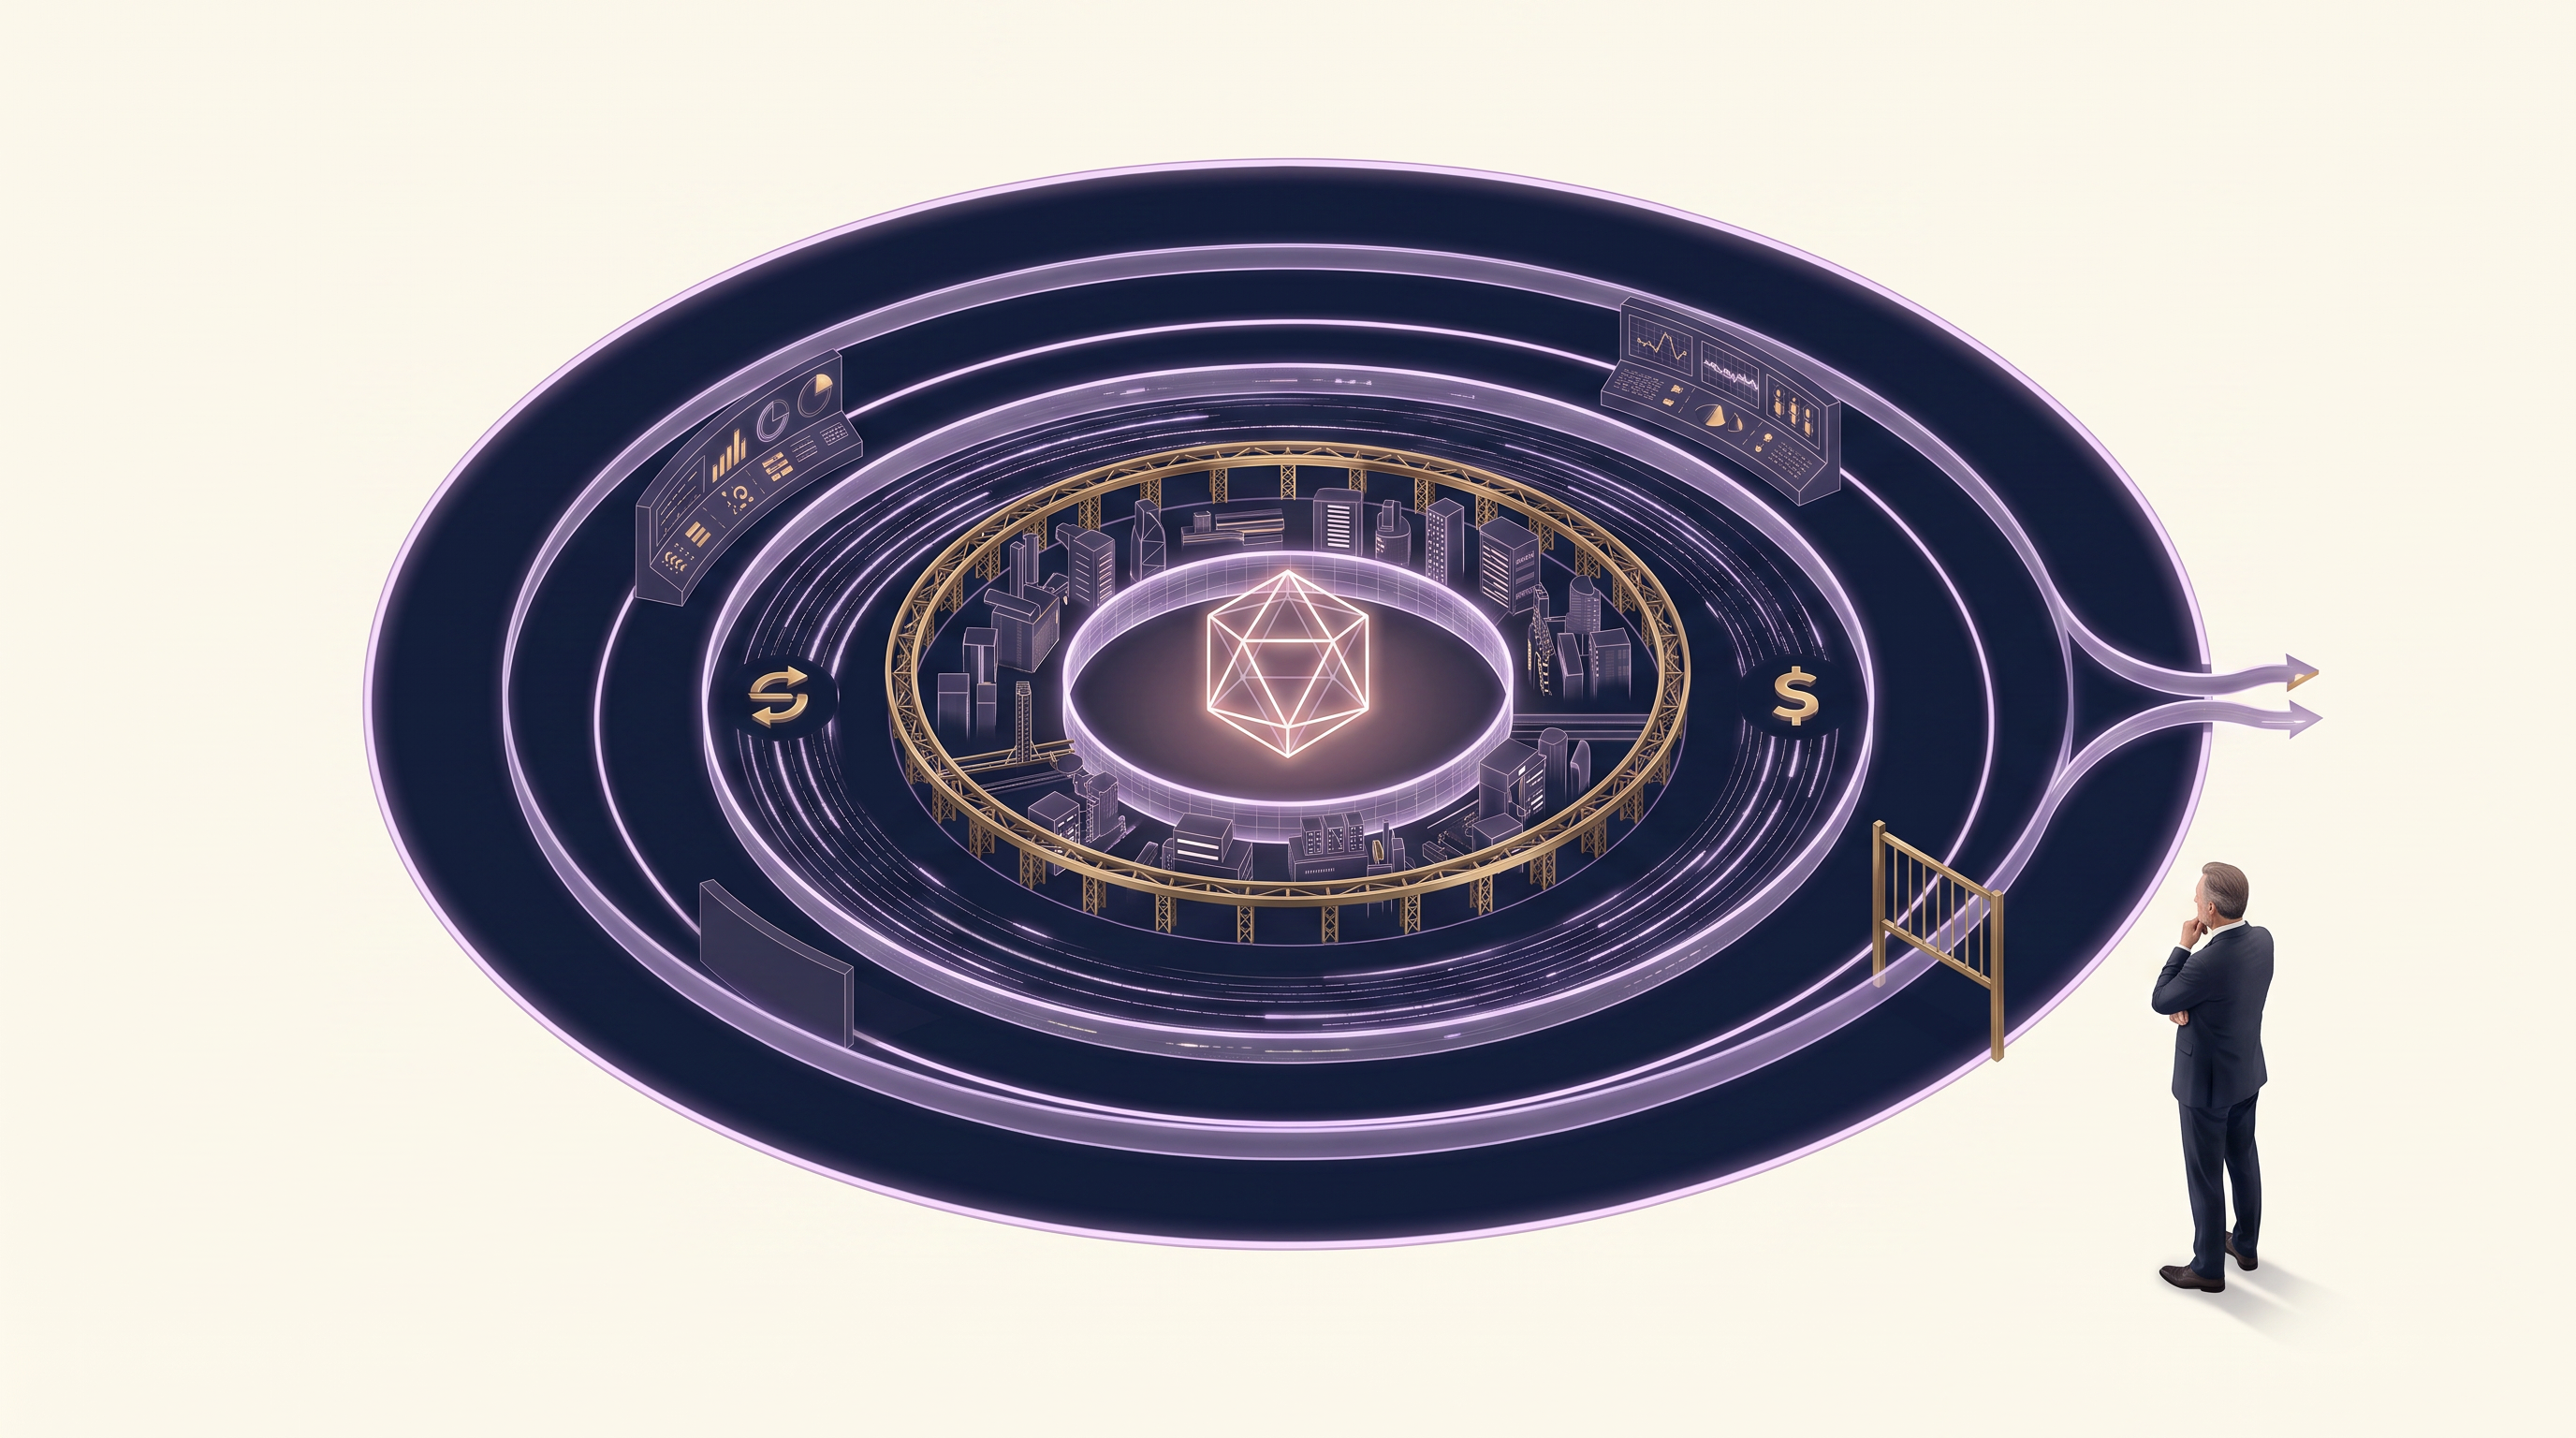
Dependency is not failure. Hidden dependency is.
Consider the distribution layer. Reuters reported that Moonshot AI was in early discussions with Microsoft, Amazon and Google about hosting its Kimi K3 open-weight model. According to the report, revenue allocation, data access and token-usage auditing were still unresolved, and there was no certainty that agreements would be reached.[3]
That is a useful distinction for any organisation, regardless of whether it ever uses Kimi K3. An open-weight model may be downloadable and modifiable. But its viable route to enterprise use may still involve hosting, metering, data terms, audit arrangements and commercial control by other parties. The model can be open while the operating relationship around it remains highly conditional.
The infrastructure layer presents a different form of the same question. CNBC reported that Anthropic had entered a roughly $45 billion arrangement with Nscale for compute capacity, attributed to two people with knowledge of confidential details. The reported capacity is expected to come online at the end of 2027. That is not a guarantee of future capacity, nor is it a reason for another business to imitate the arrangement. It is a reminder that model capability, reliable availability and physical compute are now joined up in ways that cannot be wished away by a product interface.[4]
No serious organisation is fully independent. Businesses rely on banks, cloud providers, legal frameworks, energy networks, logistics partners, software vendors and skilled people. The answer is not to pretend that every dependency can be removed.
The answer is to make the dependency visible enough to govern.
Make the operating assumption discussable
That means being able to say, in ordinary language, what work would be affected if a provider changed its price, a model version was withdrawn, a region became unavailable, an audit right narrowed, a data term shifted, or a platform changed hands. It means being able to distinguish an inconvenience from an interruption, an interruption from a control failure, and a control failure from a decision that should never have been delegated in the first place.
The businesses that struggle most are rarely those that have chosen a supplier. They are the businesses that have not noticed when a supplier relationship quietly became part of their operating model.
This is where a dependency register becomes useful. Not as a compliance ritual, and not as a document that sits untouched in a shared folder, but as a way of making a real operating assumption discussable.
The value is not in completing a set of fields. The value is in discovering the sentence your organisation could not previously say: “If this changes, this work stops, and this is who needs to decide what happens next.”
- 1Critical workflow — What work depends on this layer?
- 2Control point — Who currently controls it?
- 3Assumption — What must remain true for this workflow to work?
- 4Evidence — What shows that the assumption is true today?
- 5Degraded mode — What happens if it is no longer true?
- 6Human authority — Who decides whether to continue, change or stop?
The decision about dependency remains human
No tool can tell an organisation what level of dependence is acceptable. A system can surface a supplier change, compare price movements, map a technical dependency or highlight an expiring agreement. It can even recommend an option against criteria that people have already set.
It cannot decide what the business is prepared to rely on.
That is a judgement about resilience, customer responsibility, contractual obligation, operational risk and the direction of the organisation. It requires someone to decide what evidence is enough, what contingency is viable and where a system should stop and escalate.
In an essay published on 26 August, Bill Gates argued that the choices made during the AI transition are critical and that leaders are not preparing adequately. That is a personal policy argument, not evidence that one technology strategy is correct. Its value here is simpler: some choices should be retained deliberately, even when a system could technically optimise part of the process.[5]
The choice to accept an AI dependency is one of them.
An organisation can use AI to work faster, see more, prepare better and route work more intelligently. It can do all of that while remaining clear that a person must own the terms of reliance. The person decides whether the evidence is sufficient. The person decides whether the fallback is credible. The person decides what to do when the assumption fails.
AI may surface the dependency.
A named human owns the terms of reliance.
The decision to continue, change or stop remains human.
The route out is part of the route in
Before adopting an AI capability, ask one final question: if this provider, model, platform, region or commercial arrangement changes, how do we continue safely?
The answer does not need to be a fantasy of total independence. It needs to be honest. It may be a degraded manual process. It may be a second provider. It may be a delayed workflow. It may be a decision that some work should not depend on the system at all.
But it must be an answer.
The route out is part of the route in. If you cannot explain how a critical AI-enabled workflow would slow down, change or stop safely, then you do not yet understand the dependency you are creating.
And if “open” is the only answer you have, you may have confused visibility with control.